Run AI locally: RAG, hosting and data protection
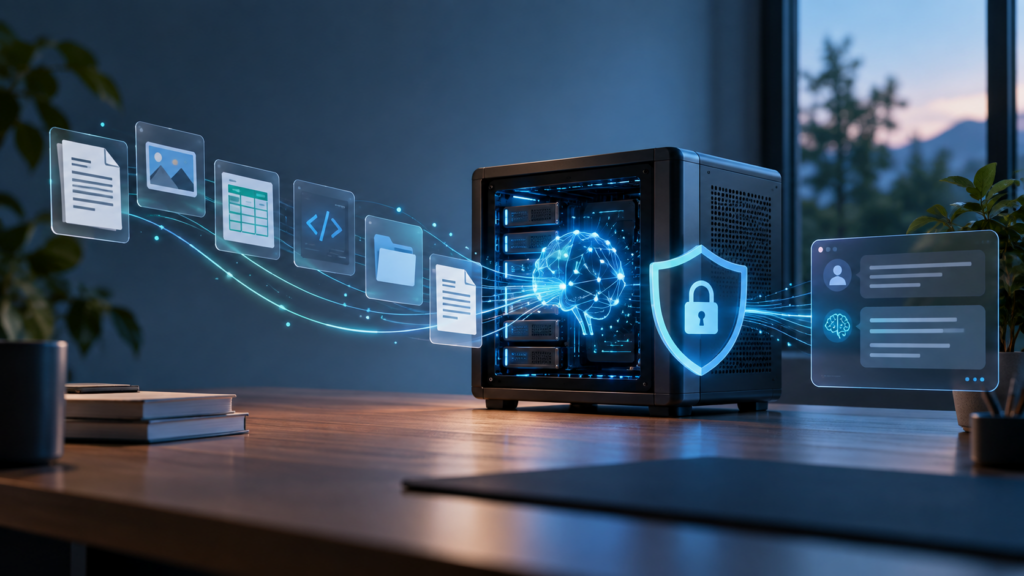
Local AI now means much more than an offline chatbot running on a single computer. Language models can work with internal documents, retrieve data from existing systems, classify requests and support complete workflows together with speech and automation components.
Not every component has to run on the same machine. A model can run on local hardware, on a self-managed server in a data centre or on managed infrastructure where the processing location and contractual conditions can be selected more deliberately.
Many narrowly defined tasks also do not require one of the largest available models. If the use case is limited and the required knowledge is supplied from external data sources, smaller models can be sufficient.
This article explains the main deployment options, the role of retrieval-augmented generation, when fine-tuning is useful and why a server located in Germany or the EU does not automatically make an AI application compliant with data protection law.
What does local AI actually mean?
In the strictest sense, local AI runs completely on a device or inside an organisation’s own network. Prompts are processed there and the model produces its output without calling an external model service for inference.
In practice, the term is often used more broadly. An organisation may manage a model itself while the physical hardware is located in a data centre. This is no longer local in the sense of running on the user’s own computer, but control over the model, software and data flow can still be substantially greater than with a public AI service.
Local computer
      |
      v
Internal network
      |
      v
Self-managed server in a data centre
      |
      v
Managed model service
      |
      v
Public AI service
Where can a language model run?
1. On a local computer
For testing, internal tools or workloads with moderate requirements, a model can run directly on a workstation. Model weights, prompts and outputs can remain on the device as long as no additional external services are involved.
The main limits are memory, GPU memory, memory bandwidth and compute performance. Smaller or quantised models can reduce hardware requirements, although they do not automatically provide the same quality as larger models.
2. On a server inside the local network
If several users or applications need access to the same model, a central internal server may be more practical. The model is deployed once and several applications communicate with it through an internal interface.
Employees
Applications
Automations
     |
     v
Internal model interface
     |
     v
Own AI server
3. On a self-managed server in a data centre
A self-managed AI server does not have to be physically located in the same building. Data centres offer servers with powerful GPUs that can run custom models and applications.
The hardware is hosted externally, while the operating system, model server, access rules and application can still be managed by the organisation itself.
4. Through a managed model service
With managed model serving, a provider operates the model infrastructure and exposes an interface for inference. Depending on the service, region, model selection, retention rules and contractual conditions can be specified.
From an application’s perspective this can look similar to an ordinary AI API. The difference is that the infrastructure and processing conditions can be selected more deliberately than with a generic public chatbot.
Deployment models compared
| Deployment | Direct control | Operational effort | Typical advantage |
|---|---|---|---|
| Model on a local computer | very high | medium | data and model can remain fully local |
| Own server on the internal network | very high | high | central AI service for internal applications |
| Self-managed server in a data centre | high | high | more hardware capacity without local servers |
| Managed model service | depends on service and contract | lower | less infrastructure administration |
| Public AI service | depends on provider | very low | fast access and broad model selection |
Why smaller models can be enough for specialised tasks
A general-purpose assistant is expected to handle programming, writing, image understanding, knowledge questions and complex reasoning. A model inside a defined business process often has a much narrower task.
It may only need to classify a message, extract a few fields or create a response from information that has already been retrieved from approved sources.
In such cases, performance on broad general benchmarks is not the only relevant criterion. Reliability on the specific task and access to the right data can matter more.
RAG: knowledge does not have to live inside the model
Many applications require current or internal information. Product data, technical documentation, policies and customer information change frequently and are therefore poor candidates for knowledge that has to be permanently embedded in a model.
Retrieval-augmented generation, or RAG, keeps this knowledge outside the language model. Before a response is generated, the system retrieves relevant information from a data source and provides only that context together with the request.
Question
  |
  v
Search documents or database
  |
  v
Relevant passages
  |
  v
Language model
  |
  v
Answer based on supplied context
The German Data Protection Conference describes RAG as a method for combining language models with organisation-specific knowledge sources. Its guidance also notes that RAG can enable smaller and locally operated models.
The German Federal Commissioner for Data Protection and Freedom of Information points out that information stored in a RAG system can be changed or deleted more easily than knowledge embedded in a language model. It also notes that smaller models may be sufficient when relevant information is supplied by the database.
Does a custom AI application require model training?
For many specialised applications, a language model does not have to be trained from scratch. Training a foundation model requires large data sets and substantial computing resources and is usually not the appropriate starting point for an ordinary application.
| Method | Purpose | Changes the model? |
|---|---|---|
| Prompting | describe the task, rules and desired output | No |
| RAG | add current or internal knowledge to the request | No |
| Fine-tuning | adapt behaviour for recurring tasks | Yes |
| Training from scratch | create a new foundation model | Yes, completely |
If a model needs access to internal documents, RAG is often more appropriate than fine-tuning. Fine-tuning can be useful when the model needs to perform the same classification, structure or output behaviour consistently.
How a language model becomes a complete AI system
A language model by itself receives text and produces text. Real workflows usually require additional components.
Email
Web form
Phone
   |
   v
Text or speech recognition
   |
   v
Analyse request
   |
   +----> documents
   +----> CRM
   +----> ERP
   +----> calendar
   |
   v
Language model
   |
   v
Response or defined action
The model does not have to memorise all customer or product data. It can determine which information is required and receive that information from the appropriate system.
Example: written requests
An incoming message can first be classified. If it concerns an order, the system can retrieve order information. If it contains a technical question, relevant parts of a documentation set can be retrieved.
Example: phone calls
Speech introduces additional components. Audio can be converted to text, processed by a language model and converted back into speech for the response.
Call
  |
  v
Speech recognition
  |
  v
Text
  |
  v
Language model and data sources
  |
  v
Response text
  |
  v
Speech synthesis
Call recording, transcription and personal conversation data can create additional legal and data protection requirements that need to be assessed separately.
The language model is only one part of the data flow
For self-hosted AI, the location of the language model alone is not enough to describe the architecture. A workflow may include speech services, document stores, vector databases and external tools, each with its own data connections.
For every component it should therefore be clear which data it receives, where that data is processed and whether it is stored or used for additional purposes.
A server in Germany does not automatically make an AI system GDPR-compliant
Infrastructure location can be important for data protection, contractual arrangements and international data transfers. It does not by itself determine whether a specific processing activity is lawful.
Purpose, legal basis, type of personal data, access rights, retention periods, processors and other recipients may all be relevant.
The European Data Protection Board explicitly takes a case-by-case approach to questions such as whether an AI model can be considered anonymous or whether a specific legal basis applies.
RAG does not remove these requirements either. The German Data Protection Conference stresses that transparency, purpose limitation and data subject rights still have to be addressed across the complete system.
When does local or more controlled AI make sense?
Self-hosted or more controlled infrastructure can be useful when sensitive internal information is processed regularly, a narrowly defined process is being automated or a model is integrated permanently into existing systems.
Typical technical use cases include internal document assistants, information extraction, classification, recurring request processing and AI functions embedded inside existing software workflows.
Hybrid architectures are also possible. A smaller self-hosted model may handle standard cases while exceptional tasks are routed to a stronger external service. In that case, the data allowed to follow that route must be defined explicitly.
When can an external cloud service still be the better fit?
Self-hosting is not automatically the best solution. Very large models, demanding image or video generation and highly variable workloads can be easier to operate in the cloud.
There is also an operational cost to self-hosting. Models need updates and monitoring, hardware can fail and security issues have to be addressed.
The practical decision is therefore not simply local versus cloud. It is often more useful to decide which components require direct control and where an external service is acceptable.
How I would build a prototype
For an initial test, I would not start with a complete AI system containing telephony, document retrieval and several business applications.
The first step should be a single narrow task that can be tested with a limited data source.
Real example requests
        |
        v
Small document set
        |
        v
RAG
        |
        v
Language model
        |
        v
Testable output
Only after that workflow is reliable should additional data sources or actions be added. This makes it easier to evaluate model quality, retrieval and process logic separately.
The application should ideally access the model through an internal abstraction layer so that a local model can later be replaced by a server or another model service without rebuilding the complete application.
Conclusion
Local AI is no longer limited to a simple offline chatbot. Language models can be part of larger systems that search documents, retrieve data from existing applications, process speech and prepare or execute defined actions.
Clearly defined tasks do not always require one of the largest models. RAG can provide current domain knowledge externally and make smaller models more practical. Fine-tuning is an additional option when the desired change concerns behaviour rather than knowledge.
Whether the system runs on local hardware, a rented server or managed infrastructure is ultimately an architecture decision. Location can influence control and data flows, but it does not replace an assessment of the actual processing activities.
If you want to evaluate whether a self-hosted or more controlled AI workflow is suitable for an existing process, a small prototype is usually more informative than choosing a model in the abstract.
In 15 minutes we can clarify without obligation which architecture fits your data, existing systems and requirements. Book a first conversation.
Collaboration
Custom AI and automation solutions, fitted to process, data risk and cost.
Get in touch →Blog
New articles by email. No ads.